AI crawler access:
Let search bots read your pages without JavaScript
An AI engine can only cite pages its crawler can reach and read. Allow the search bots, such as OAI-SearchBot, PerplexityBot and Claude-SearchBot, in robots.txt. Put key content in the server HTML, because the major AI crawlers do not run JavaScript. Then fix the 404s and redirects they hit.
major AI crawlers rendered JavaScript in Vercel’s study (vendor data)
Vercel, Dec 17, 2024GPTBot requests on Vercel’s network in one month
Vercel, Dec 17, 2024of ChatGPT crawler fetches hit 404 pages
Vercel, Dec 17, 2024of the web is served by Cloudflare, which blocks AI crawlers by default on new domains
Cloudflare, Jul 1, 2025Which AI bots should robots.txt allow?
Each company runs different bots for different jobs. Search and user bots decide whether you can be cited. Training bots only decide whether your pages train models. Allow the search bots, then make a deliberate choice on training.
AI crawlers and what to do with each:
Search bots get in, training is your call
| Bot | Job | Recommended rule |
|---|---|---|
 OAI-SearchBot | ChatGPT search | Allow. Blocked sites do not appear in ChatGPT search answers. |
| ChatGPT-User | Visits when a user asks | Allow. robots.txt rules may not apply to it. |
| GPTBot | Model training | Your call. Blocking opts you out of training only. |
 PerplexityBot | Perplexity search | Allow. Not used to train foundation models. |
 Claude-SearchBot | Claude search quality | Allow. Blocking may reduce visibility in Claude. |
| ClaudeBot | Model training | Your call. |
 Google-Extended | Gemini training token | Your call. Does not affect Google Search or AI Overviews. |
What does Crawl Insights check?
Crawl Insights audits whether AI crawlers can reach and read your site, from robots.txt to server-side rendering and page speed. A good sign is every critical row passing. A warning sign is a Fail on robots.txt or rendering, which blocks every later stage.
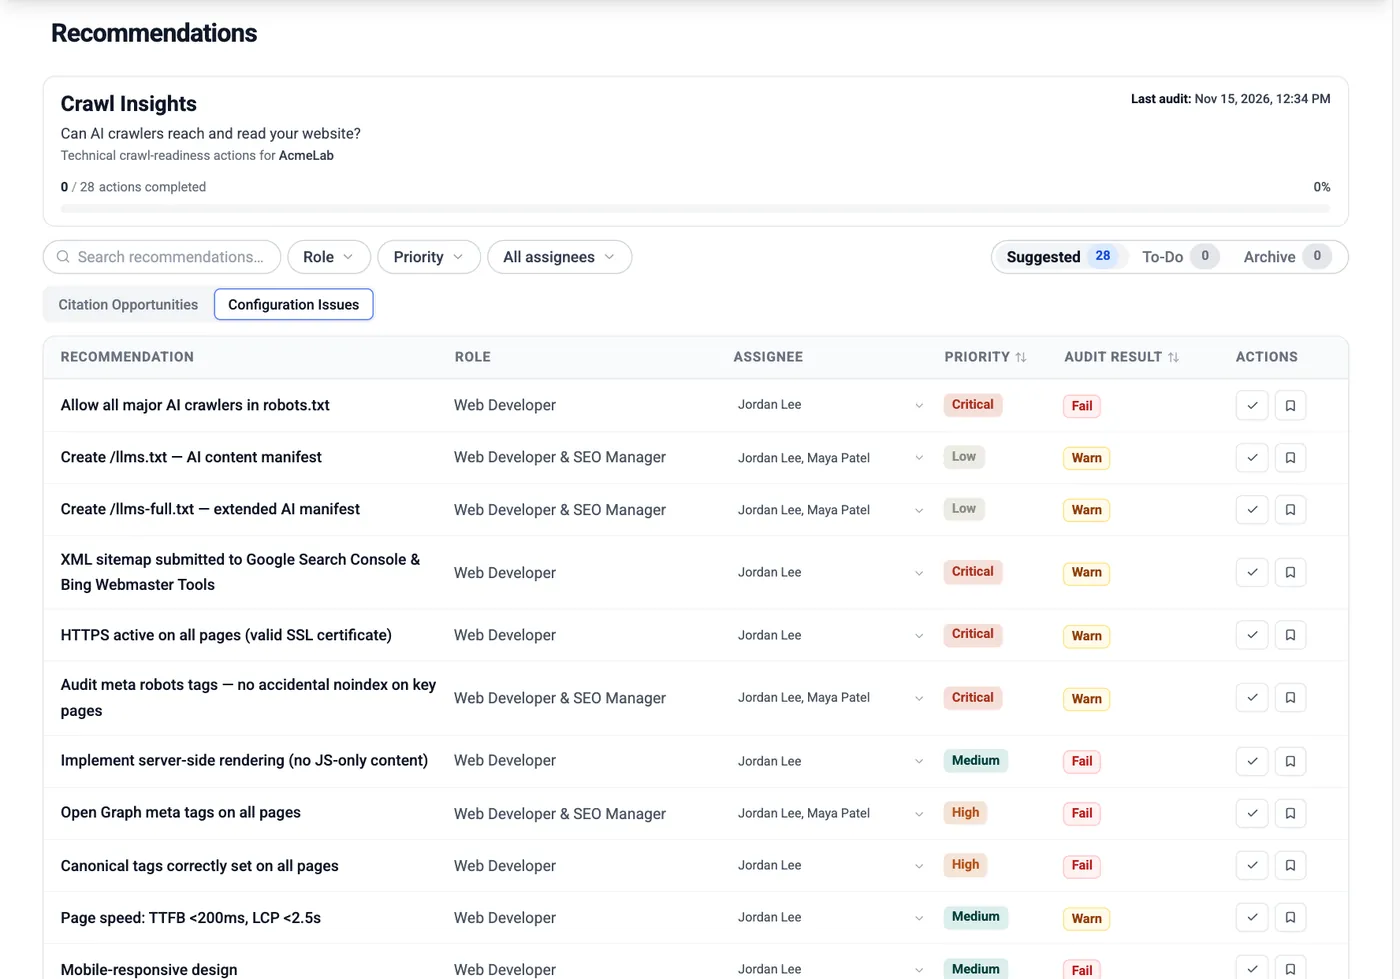 1234
- 1Progress on 28 crawl-readiness actions.
- 2Two views: citation opportunities and configuration issues.
- 3Allow all major AI crawlers in robots.txt, marked critical.
- 4Pass, Warn or Fail from the latest audit.
What else blocks AI crawlers?
- Server-render key content: crawlers fetch JavaScript files but do not run them
- Check Cloudflare or your CDN: new Cloudflare domains block AI crawlers by default
- Fix 404s and redirect chains that AI bots hit, found in your server logs
- Submit an XML sitemap with accurate lastmod dates to Google and Bing, and use IndexNow
- Treat llms.txt as optional: Google says no AI system currently uses it
Bing says it reads lastmod as a key freshness signal and ignores changefreq and priority. Google says no special AI files or markup are needed for AI Overviews or AI Mode.
Research for this lesson.
Our own studies behind this lesson. Each one has the key charts and numbers, and a link to the full article.
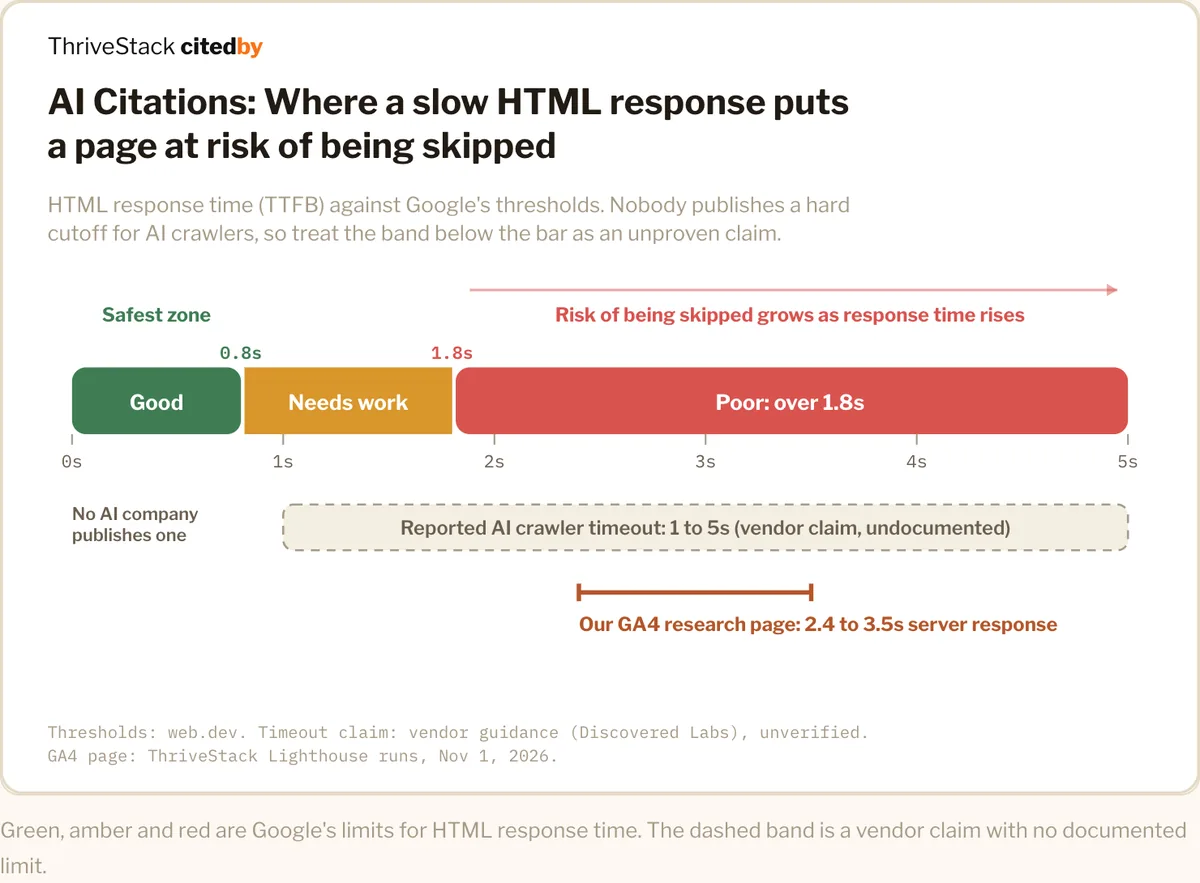
ThriveStack citedby audits crawl readiness, reads your server logs for AI bot visits and errors, and lists each fix with an owner and priority.
AI crawler access, answered.
Should I block GPTBot?
Only if you do not want your content used for training. Blocking GPTBot does not remove you from ChatGPT search, which uses OAI-SearchBot.
Do AI crawlers run JavaScript?
Vercel found none of the major AI crawlers rendered JavaScript in its study. Put the content you want cited in the server HTML.
Do I need llms.txt?
It is optional. Google’s John Mueller said no AI system currently uses it, and Google says no special AI files are needed.
Does Google-Extended affect AI Overviews?
No. Google says Google-Extended does not affect inclusion in Google Search. AI Overviews follow normal Googlebot rules.
All 10 questions this page answers.
These questions come from a query fan-out of "how to win AI search visibility". Each one has a short answer here, and the lesson above goes deeper.
How to allow OAI-SearchBotImplementation
In robots.txt add a "User-agent: OAI-SearchBot" group with "Allow: /", and check that your CDN or firewall does not block it. OpenAI says robots.txt changes take about 24 hours to apply. Then confirm in server logs that it gets status 200.
How to allow PerplexityBotImplementation
Add a "User-agent: PerplexityBot" group with "Allow: /" and check your CDN and firewall rules. Perplexity says changes can take up to 24 hours. Confirm in server logs that PerplexityBot gets status 200 on the pages you want cited.
AI crawler robots.txt best practicesCommercial
Allow the search and user bots, decide on training bots on purpose, avoid blanket Disallow rules, and keep the file at your domain root. Recheck after any CDN change: Cloudflare has blocked AI crawlers by default on new domains since Jul 1, 2025.
GPTBot vs OAI-SearchBotCommercial
GPTBot collects content that may train OpenAI models. Blocking it opts you out of training. OAI-SearchBot powers ChatGPT search, and blocking it keeps you out of search answers. You can block GPTBot and still allow OAI-SearchBot.
AI bot access blocked by CloudflareTroubleshooting
Cloudflare blocks AI crawlers by default on new domains since Jul 1, 2025, and it serves about 20% of the web. Review the AI crawler and bot settings in your Cloudflare dashboard, allow the search bots you want, then confirm in logs that they get status 200.
How to test AI crawler accessImplementation
Read robots.txt for each bot, request a page with the bot’s user agent to see the status code, and check server logs for real visits. A 200 means the bot got the page. A 403, 404 or redirect loop means it did not.
AI crawler IP verificationInformational
Anyone can fake a user agent, so check that the request comes from the IP ranges the bot’s owner publishes, or confirm it with a reverse DNS lookup. ThriveStack citedby counts only IP-verified bot fetches when it matches crawls to citations.
ChatGPT-User vs OAI-SearchBotCommercial
OAI-SearchBot crawls ahead of time for ChatGPT search. ChatGPT-User visits a page when a user’s question needs it, and OpenAI says robots.txt rules may not apply to it. A ChatGPT-User hit in your logs means a live user question.
How to check AI bot server logsImplementation
Filter your logs by AI user agents such as GPTBot, OAI-SearchBot, ChatGPT-User, ClaudeBot and PerplexityBot. Look at pages, status codes and dates. Seer suggests comparing their status codes with Googlebot’s and fixing redirects and errors. ThriveStack citedby reads logs from Vercel, WordPress or a Cloudflare Worker.
Does blocking AI training bots affect AI search?Informational
Mostly no. Blocking GPTBot opts out of OpenAI training, not ChatGPT search. Google says Google-Extended does not affect inclusion in Google Search. Blocking ClaudeBot stops Claude training, while blocking Claude-SearchBot or Claude-User may cut Claude search visibility.
Sources for this lesson
- OpenAI: Overview of OpenAI crawlers Checked Nov 17, 2026
- Perplexity: Perplexity crawlers Checked Nov 17, 2026
- Anthropic: Does Anthropic crawl data from the web Updated Oct 30, 2026
- Google Search Central: Google common crawlers Google-Extended
- Vercel: The rise of the AI crawler (Dec 17, 2024) Vendor claim, Vercel network data
- Cloudflare: Default AI crawler blocking (Jul 1, 2025)
- Bing Webmaster Blog: Sitemaps in AI-powered search (Jul 31, 2025)
- Search Engine Roundtable: John Mueller on llms.txt (Jun 18, 2025)
- Google Search Central: AI features and your website Checked Nov 17, 2026
Figures were checked against each page on Nov 17, 2026. Vendor studies are labelled as vendor claims.