AI crawler logs research:
How to find and fix AI citation gaps
AI crawler logs are server records of each request an AI bot makes to your site: its name, the page and the status code it got. They show which bots reached you, which were blocked and which never came. Matching them to tracked prompts finds the citation gaps to fix first.
GPTBot fetches in one month on Vercel, none ran JavaScript
ThriveStack citedby researchpages Anthropic crawled per referral, 28 days to Aug 1, 2026
ThriveStack citedby researchof ChatGPT bot fetches hit a missing page
ThriveStack citedby researchbetter conversion for AI referred visits, US retail, Jul 2026
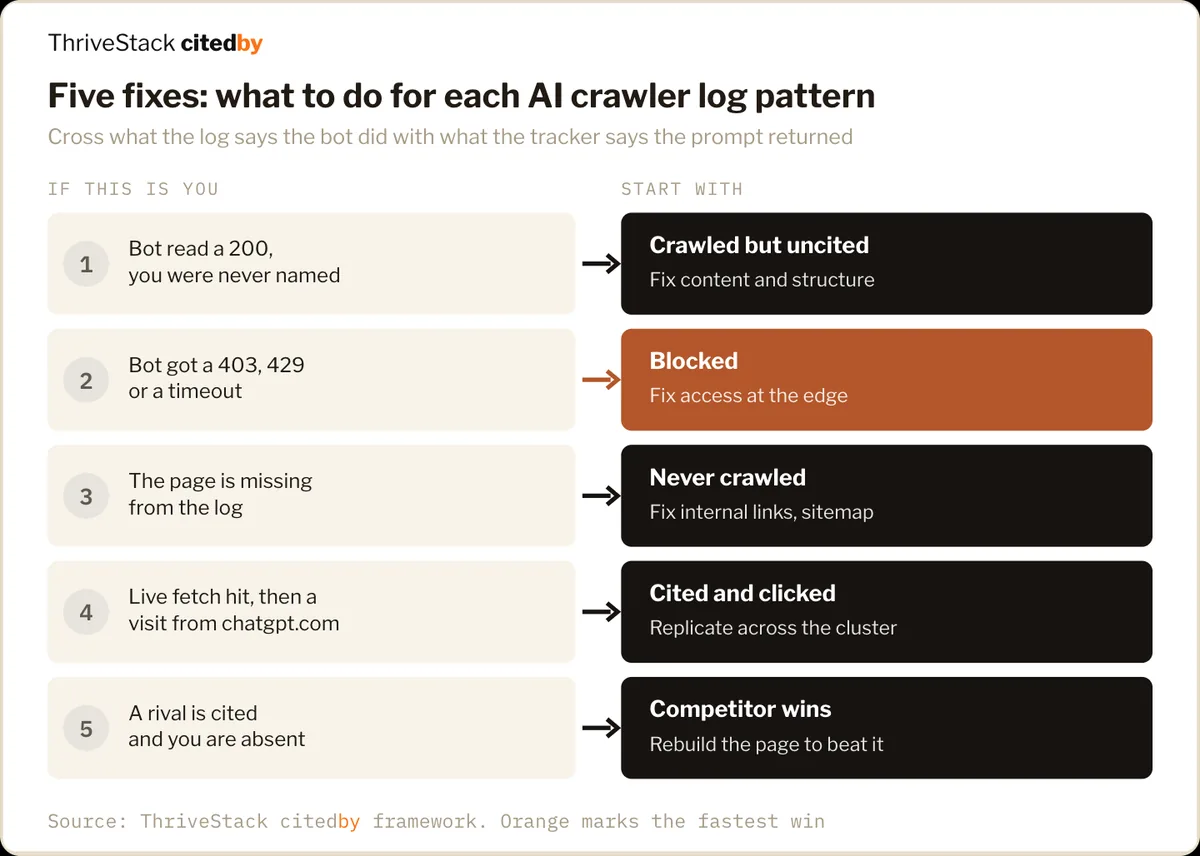
ThriveStack citedby researchWhat should you do for each log pattern?
Five fixes, one for each AI crawler log pattern: crawled but uncited, blocked, never crawled, cited and clicked, and competitor wins.
How do you use this in the course?
Use it in lesson 6.4, track with ThriveStack: connect a server log source so AI crawler and agent visits are counted per page, then list the pages they read but never cite. Open the lesson →
ThriveStack citedby turns this research into actions for your own brand: tracked prompts, ranked fixes and attribution to revenue.
Sources for this lesson
Figures were checked against each page on Nov 17, 2026. Vendor studies are labelled as vendor claims.