AI visibility tracking research:
Why the same prompt returns different brands
Fewer than 1 in 100 repeat runs return the same brands. That breaks rank tracking, but measurement still works. This report explains why AI engines answer differently almost every time, and gives the sample sizes and confidence intervals needed to measure AI visibility without fooling yourself.
unique completions from 1,000 identical prompts at temperature 0
ThriveStack citedby researchsource overlap between ChatGPT and Perplexity on the same prompt
ThriveStack citedby researchstandard error of a single-run detection rate
ThriveStack citedby researchof AI Mode citations absent from the organic top 10
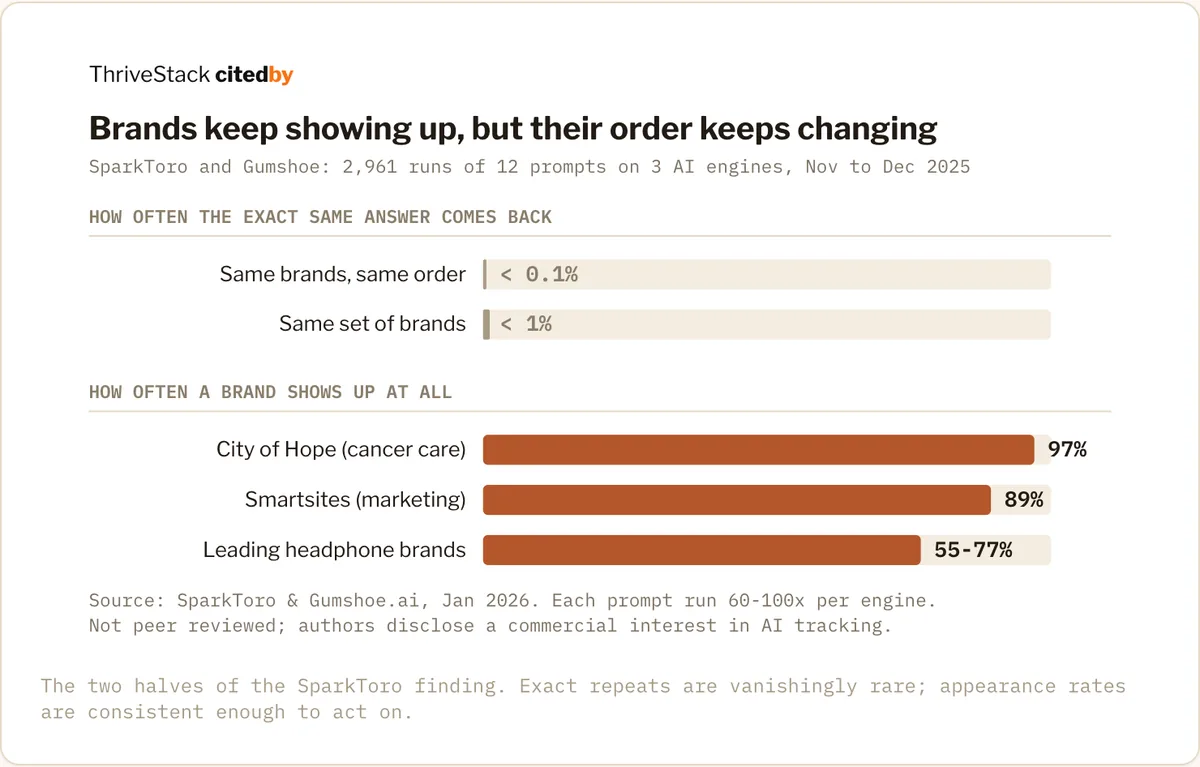
ThriveStack citedby researchIf the order changes, what stays steady?
Brands keep showing up, but their order keeps changing. Exact repeats are vanishingly rare, while how often a brand appears is consistent enough to act on.
How do you use this in the course?
Use it in lesson 5.1, track a prompt baseline: measure visibility across many runs, never a single rank. Open the lesson →
ThriveStack citedby turns this research into actions for your own brand: tracked prompts, ranked fixes and attribution to revenue.
Sources for this lesson
Figures were checked against each page on Nov 17, 2026. Vendor studies are labelled as vendor claims.