Crawled but not cited:
Fix the pages AI reads and skips
The cheapest AI search wins are pages AI already reads but never cites. Match AI bot visits in your server logs against the pages cited in your prompt runs. A page with many ChatGPT-User or Perplexity-User hits and no citations has a weak or buried answer. Fix its opening, structure and entity signals first.
pages OpenAI crawled for each visit it sent back, Jul 2025
Cloudflare, Aug 29, 2025verified AI fetches to AI-referred visits on two sites (vendor claim)
Clickport, Jul 7, 2026AI bot requests in 60 days in the demo workspace
ThriveStack citedby demo, Nov 2026pages monitored in the demo content audit, with scores and citations
ThriveStack citedby demo, Nov 2026Why start with pages AI already crawls?
A crawl means the engine found and read the page. If it still does not cite it, the problem is usually the page itself: no direct answer, a buried number, weak entity signals. That is faster to fix than getting a new page crawled. OpenAI and Perplexity say their user-triggered fetchers may ignore robots.txt, so a ChatGPT-User or Perplexity-User hit is a live user question.
How does the Content Audit show it?
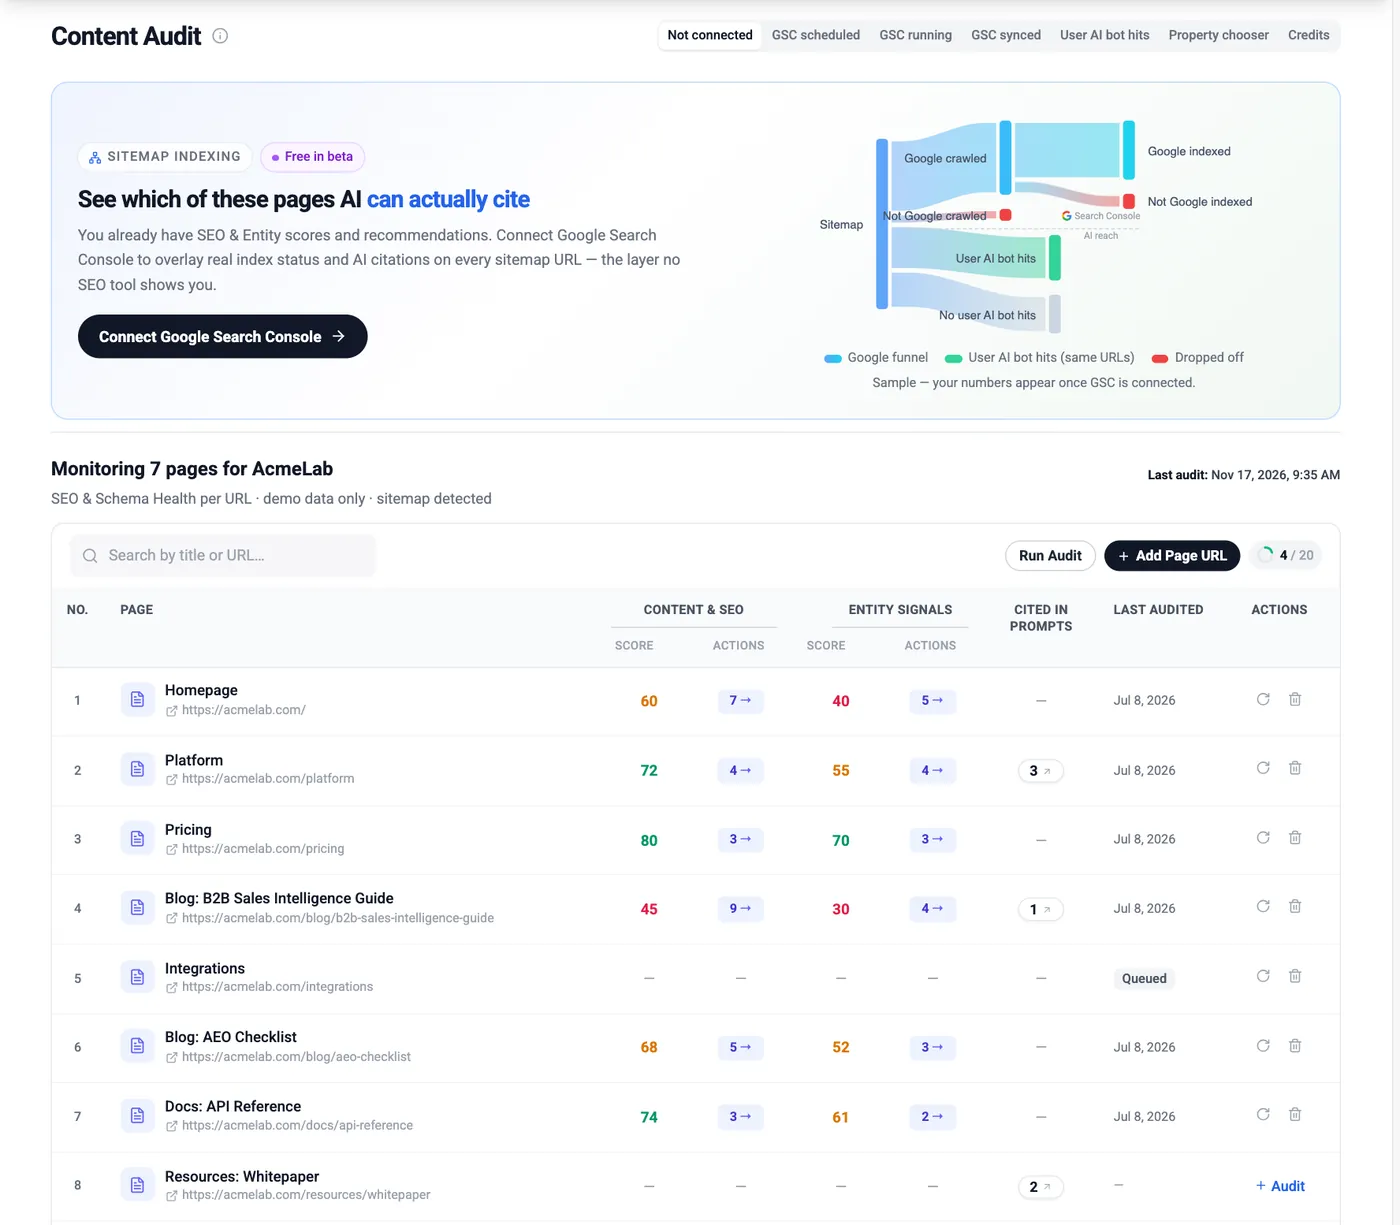
Content Audit joins Google index status, AI bot hits and citations for each sitemap page. A good sign is high scores on pages that are cited in prompts. A warning sign is a page with user AI bot hits, low scores and no citations.
 1234
- 1Sitemap to Google crawled and indexed, plus user AI bot hits on the same URLs.
- 2Connect Google Search Console to overlay real index status.
- 3Content and SEO and Entity scores per page, with open actions.
- 4How many tracked prompts cite each page.
How do you fix a crawled but uncited page?
Check what the bot got
In the logs, check the status codes. Seer suggests comparing AI bot status codes with Googlebot and fixing redirects and errors first.
Find the prompt it should win
Match the page to the tracked prompts on its topic. Read the answers to see what the engine cited instead.
Rewrite the opening
Add a 40 to 60 word direct answer, a sourced number and a table, as in lesson 3.1.
Re-run and compare
Let the next runs finish and compare citations with the baseline from lesson 5.1.
ThriveStack citedby reads AI crawler hits from your server logs, joins them with Search Console and your prompt runs, and shows which pages AI reads but never cites.
Crawled but not cited, answered.
What does crawled but not cited mean?
An AI bot fetched the page, but the engine did not cite it in answers to your tracked prompts.
Does a crawl prove the page was used?
No. A fetch shows the page was read, not that the answer used it. Clickport makes the same warning about its own data.
Which logs do I need?
Server logs from your host or CDN. ThriveStack citedby reads them from Vercel, WordPress or a Cloudflare Worker, and keeps only AI crawler requests.
Sources for this lesson
- Cloudflare: The crawlers that never click (Aug 29, 2025) Crawl to refer ratios
- Clickport: The AI citation gap (Jul 7, 2026) Vendor claim, two sites
- Seer Interactive: Are log files the new impressions? (May 13, 2025)
- ThriveStack: Server logs and AI search citation gaps (Oct 31, 2026) Our own research
- OpenAI: Overview of OpenAI crawlers Checked Nov 17, 2026
- Perplexity: Perplexity crawlers Checked Nov 17, 2026
- ThriveStack docs: AI Crawl Attribution with Vercel Our own product docs
- ThriveStack docs: AI Crawl Attribution with WordPress Our own product docs
Figures were checked against each page on Nov 17, 2026. Vendor studies are labelled as vendor claims.